
This teardown targets the mistakes eCommerce managers commonly make when protecting WooCommerce payment and customer data and gives operator-focused corrective actions to reduce incident blast radius. You’ll get concrete monitoring signals to prioritize, containment steps you can enact in minutes, and a recovery playbook you can test with your team.
- Why reducing blast radius matters for WooCommerce payments
- Common mistakes eCommerce managers make
- How do you design monitoring and recovery playbooks?
- Tactical teardown: mistakes and corrective actions
- Incident mini-case study: containment that shrank blast radius
- Recovery playbook and testing
- Operator resources and next steps
- FAQ
Why reducing blast radius matters for WooCommerce payments
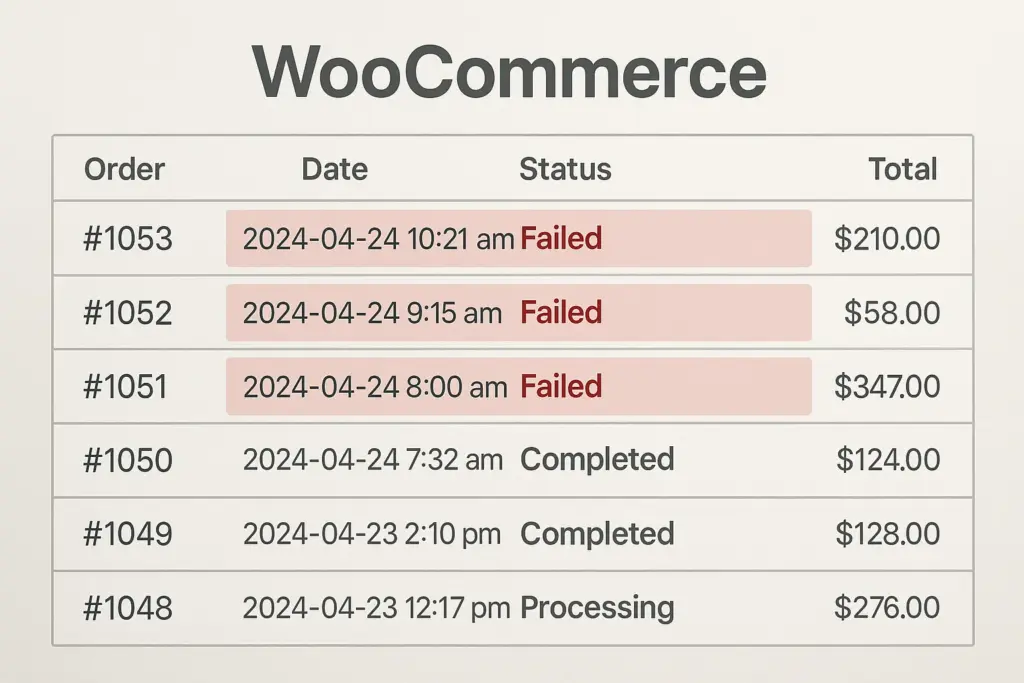
WooCommerce order log with suspicious failed payments highlighted
Payment incidents cascade: a single compromised admin user, exposed API key, or malicious plugin can expose payment workflows, order history, and customer PII. Reducing blast radius means limiting what an attacker can touch, how far data can leak, and how long remediation takes.
Where blast radius typically starts
Common starting points are admin accounts, REST API endpoints, exposed uploads, and payment gateway credentials stored in plaintext. Identify these crown jewels first: payment API keys, webhook endpoints, and the orders table in your database.
Failing fast vs. failing loudly
Operators must balance rapid containment with preserving telemetry. Always snapshot logs and filesystem metadata before sweeping or restoring—those artifacts let you verify what the attacker did and what to test in recovery.
Segmentation reduces lateral movement
Separate responsibilities: admin dashboards, file uploads, and order-processing queues should not share credentials. Network or role segmentation prevents a single compromise from touching every layer.
Common mistakes eCommerce managers make
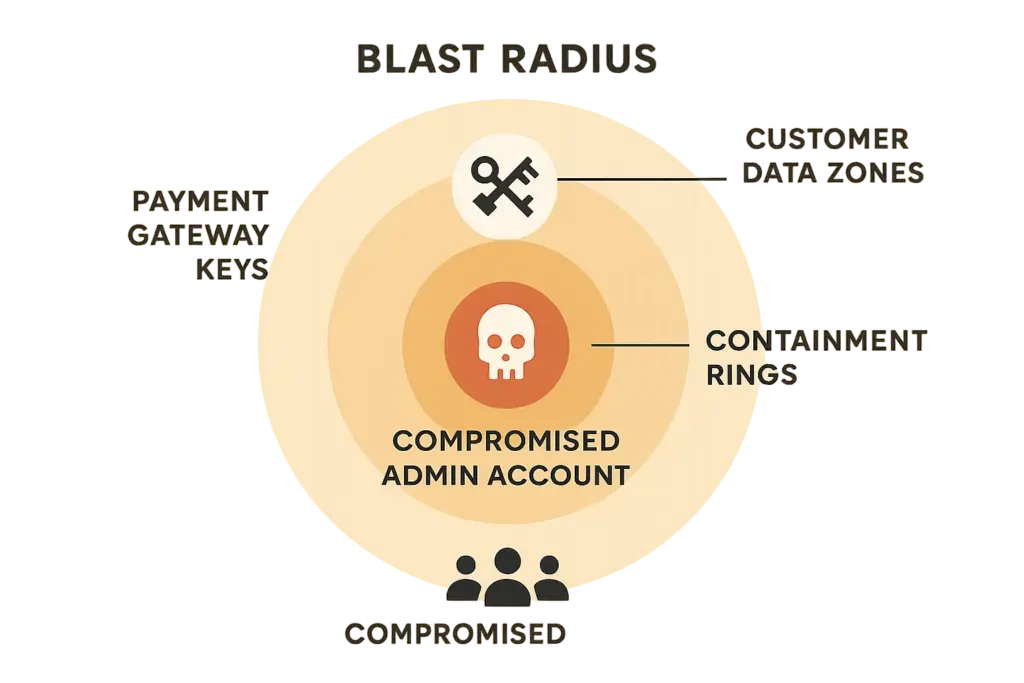
Diagram showing containment rings to illustrate blast radius reduction
Below are recurring errors I see during incident teardowns and the corrective action that operators can apply immediately.
Mistake: One admin account for everything
Correction: Enforce least privilege and unique accounts per operator. Use individual SSO identities with short-lived sessions and revoke access rather than changing shared passwords. Document role privileges and audit every admin permission change.
Mistake: No verified backups or untested restores
Correction: Verify backups include the database, uploads, and order metadata. Practice restores in an isolated environment and validate order integrity and payment gateway webhooks before returning a site to production.
Mistake: Alert fatigue — thresholds are too noisy
Correction: Tune alerts to actionable patterns: repeated payment declines across many cards, webhook signature mismatches, or rapid order creation spikes from a single IP block. Use correlation rules so multiple low-fidelity signals become a high-fidelity incident.
Mistake: Treating logs as ephemeral
Correction: Centralize logs, retain at least 90 days for payments, and ensure log timestamps and order IDs are searchable. Preserve raw webhook payloads for forensic analysis when an incident starts.
How do you design monitoring and recovery playbooks?
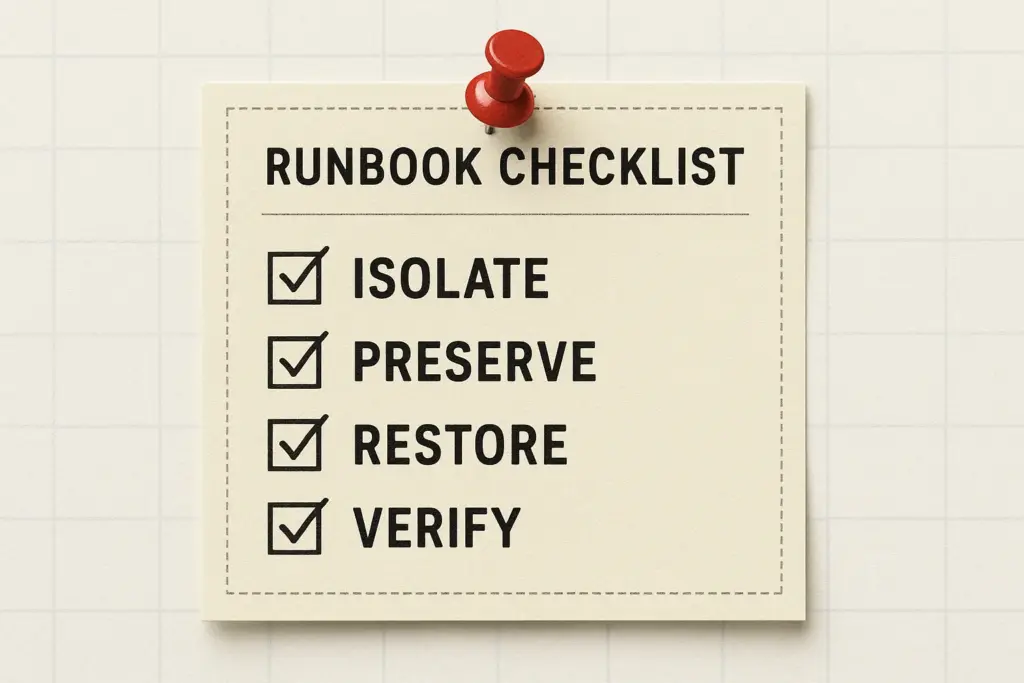
Runbook checklist card pinned on a virtual whiteboard
Start by mapping which signals indicate expansion vs. reconnaissance: order anomalies and webhook failures are expansion; odd admin SSO activity is reconnaissance. Build two playbooks: a containment playbook triggered automatically and a recovery playbook triggered once evidence is preserved.
Telemetry to prioritize
Make these sources your baseline: WooCommerce order logs, payment gateway webhook logs, server error logs, and admin login history. Linkages between these sources are the early indicators of an expanding incident.
Alerting and escalation thresholds
Define escalation rules such as three or more failed payments tied to new customer accounts within ten minutes, or a sudden increase in order metadata modifications. Escalate to an on-call operator with a single pane of correlated data.
Runbook fragments operators need
Each playbook should open with short prescriptive steps: snapshot (where to capture), isolate (which accounts to disable), preserve (what logs to copy), and restore (sequence and verification checks). Keep commands abstract—operators should have the exact CLI or UI steps in a locked internal document.
Tactical teardown: mistakes and corrective actions
This section breaks down specific error patterns and exactly how to fix them under time pressure.
Fix: Snapshot before you flip switches
When you detect a payment incident, immediately snapshot the VM or container, export the database with timestamps, and copy /wp-content/uploads and wp-config.php to a secure forensics location. If you cannot snapshot at the hypervisor level, export SQL and compress uploads to a quarantine bucket with restricted access.
Fix: Isolate compromised admin accounts
Remove the user’s sessions, revoke SSO tokens, and rotate any OAuth or API keys that account could have accessed. If the attacker likely had FTP or SSH access, rotate keys and audit authorized_keys and known hosts files for persistence artifacts.
Fix: Protect payment gateway credentials
Rotate gateway keys and revalidate webhook signing secrets. Update webhook endpoints to a maintenance URL that discards test payloads during containment, and capture original payloads for analysis.
Fix: Contain package/plugin risk windows
If a plugin is suspected, move it to a quarantine folder and test the checkout flow in staging. See our hardening guidance in the Reduce Plugin Exploit Risk During Disclosure Windows briefing for specific preparation steps that minimize exposure during public disclosures.
Incident mini-case study: containment that shrank blast radius
A mid-sized store noticed a spike in failed payments and webhook signature mismatches over ten minutes. The on-call operator immediately snapped the VM and exported the database, then disabled the suspected compromised admin account and rotated gateway keys. By preserving raw webhook payloads and correlating IP addresses in the logs, the team identified a credential stuffing tool hitting checkout endpoints. They isolated the checkout endpoint behind a temporary verification step, validated restores in an isolated staging network, and rotated keys — total customer-facing downtime was under 90 minutes and the attacker’s lateral movement was limited to a single session.
Timeline and decisive actions
Minutes 0–10: detection and snapshot. Minutes 10–30: account disable, key rotation, webhook quarantine. Minutes 30–90: validate staged restore and re-enable payment flow after verification. Post-incident: forensic review and policy changes to reduce future blast radius.
Lessons learned
The decisive wins were pre-mapped playbook steps and a tested restore procedure. Centralized logs and quick access to webhook payloads made attribution and containment straightforward.
Recovery playbook and testing
Recovery is less about heroic restores and more about repeatable verification steps that reduce mistakes during promotion back to production.
Verify backups and restore in isolation
Always validate backups by restoring to an isolated network. Confirm order totals, payment gateway signatures, and webhook replay behavior before pointing traffic back at the site.
Stepwise promotion and smoke tests
Promote staging to a pre-production environment with a small percentage of traffic or a test customer cohort. Run smoke tests that simulate successful and failed payments and replay captured webhook payloads to verify behavior.
Post-incident hardening tasks
After recovery, implement the fixes that reduced blast radius during the incident: key rotation automation, improved alert correlation, and shorter credential lifetimes. Document exactly who did what and update the playbook accordingly.
Operator resources and next steps
Use operator-focused guides to turn telemetry into precise fixes; our From Noise to Action blueprint covers how to map logs to actions. If admin access is a likely attack path, review the Admin Access Lockdown playbook to harden sessions and recovery steps. For configuration settings and how Hack Halt automates the capture and retention of the telemetry discussed here, consult the documentation.
For a practical way to implement the monitoring, key rotation, and runbook automation described above, consider Hack Halt Inc. — it accelerates capture of payment telemetry, automates snapshots for containment, and provides runbook templates operators can run quickly during incidents.
FAQ
How fast should I isolate a compromised admin account?
Isolate immediately — within minutes when possible. Disable the account, revoke API keys, and rotate credentials for any service that account could access; the faster you cut the attacker’s access, the smaller the blast radius.
What telemetry sources matter for catching payment abuse early?
Prioritize WooCommerce order logs, payment gateway webhook failures, WP error logs, and unusual admin LDAP/SSO activity. Correlating those sources reduces noise and surfaces real incidents faster.
Can I restore a site without alerting attackers or losing forensic data?
Yes — snapshot the compromised environment, preserve logs and file timestamps, then perform restores in an isolated staging network for verification before promoting. Capture forensic copies first to avoid losing evidence.
How often should recovery playbooks be tested?
At least quarterly for mission-critical stores and after any significant change (plugin update, gateway change, or infrastructure migration). Tabletop exercises monthly are ideal for small teams.